Sources#
- Claude Fable 5 and Claude Mythos 5
- Claude Opus 5 System Card
- Kimi K3 Model Card
- Recursive Self Improvement for Coding Agents
- Risk Report: August 2026 (Redacted)
- UK AISI / CAISI Preliminary Assessment of Kimi K3's Cyber Capabilities
Summary#
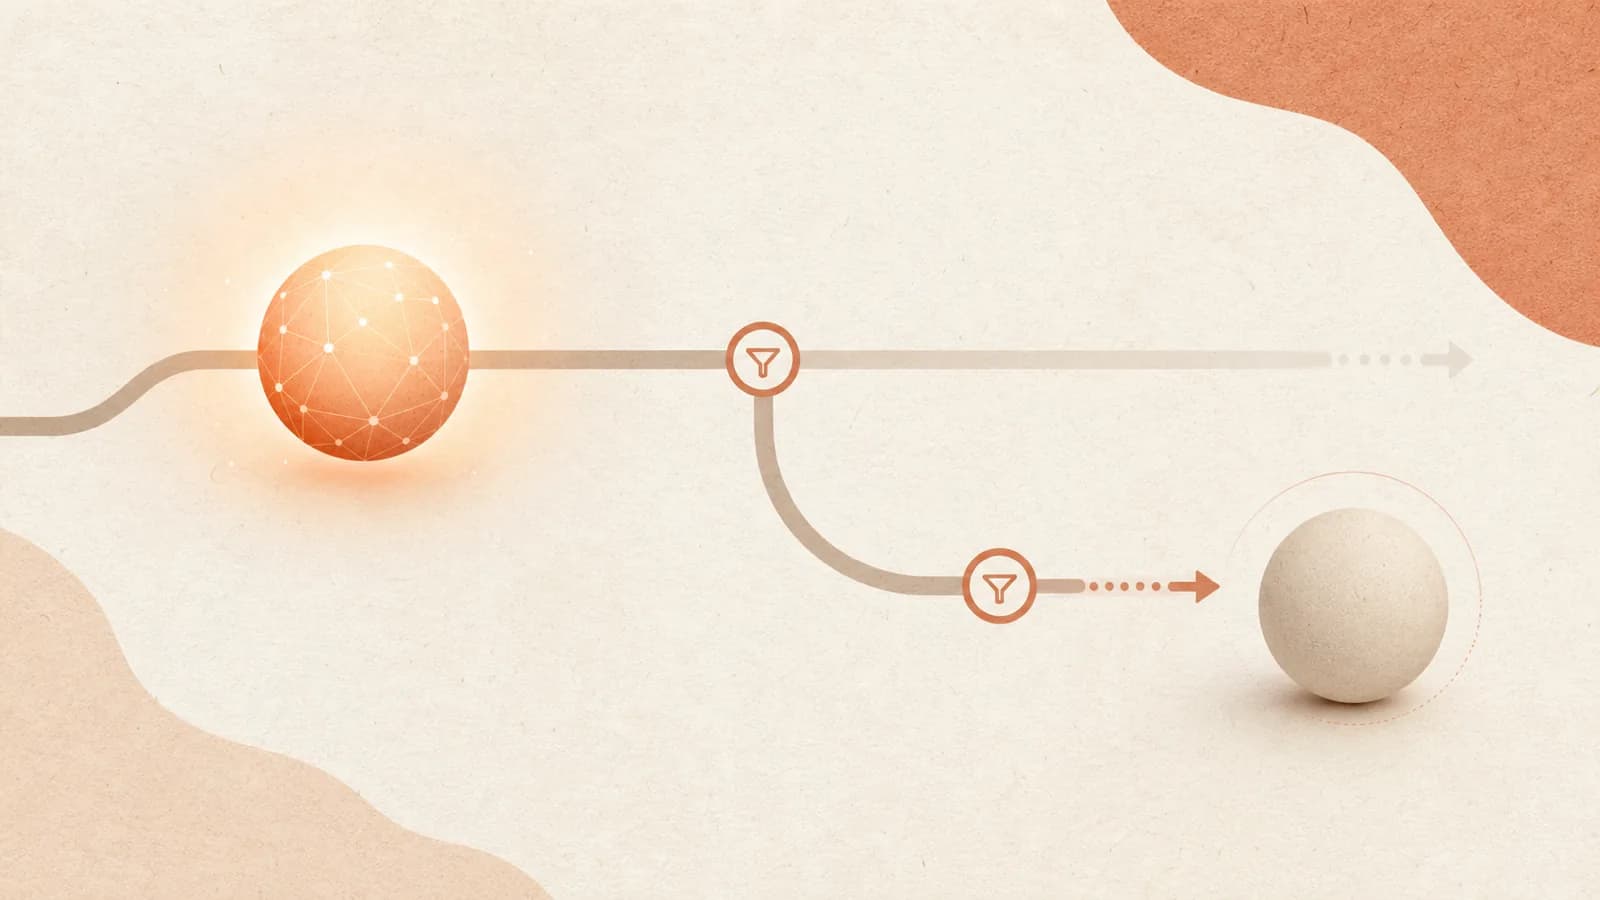
The safeguard architecture that lets Anthropic ship a Mythos-class model for general use: when separate AI classifiers detect a query in a high-risk dual-use domain (cybersecurity, biology & chemistry, or distillation), the response is automatically handled by a less-capable model — Claude Opus 4.8 — instead of Fable 5 refusing. The user is told whenever this happens. Anthropic's framing: "a response that falls back to Opus is a far better experience than an outright refusal." More than 95% of Fable sessions involve no fallback at all; the classifiers are tuned conservatively (they "sometimes catch harmless requests," triggering in "less than 5% of sessions"), accepting false positives as the price of a fast, safe release.
This is a distinct point on the safeguard spectrum. Mythos Preview was gated entirely (preview-only); Opus 4.7 differentially trained down cyber capability and blocked at inference; Fable 5 keeps the full capability in the model but interposes a classifier that swaps in a weaker model on risky topics. The capability is preserved for the >95% benign case and routed around for the rest.
Why "fallback, not refusal"#
The motivating fact is uplift: Mythos-class models could give malicious actors cyber/bio assistance "they couldn't have received from other sources." And much advanced usage is dual-use — the same query is beneficial for a defender or a researcher and dangerous for an attacker. A blanket refusal is both a bad user experience and, because it leaks which queries are "dangerous," an information signal. Falling back to Opus 4.8 — itself a highly capable model — degrades gracefully: the user still gets a competent answer, just not a Mythos-class one, on the flagged topic.
The three classifier domains#
- Cybersecurity. Covers both exploitation and offensive cyber tasks broadly (reconnaissance, discovery, lateral movement — see LLM-Driven Vulnerability Research). In a blocking-mode evaluation, "our classifiers prevent Fable from making any progress on these tasks." One external partner found Fable 5's cyber safeguards the most robust of any model tested (including Opus 4.8 and 4.7): Fable complied with zero harmful single-turn requests on cyberattack planning, exploit development, or defense evasion, whether or not any of 30 public jailbreak techniques were used.
- Biology and chemistry. Previously Anthropic blocked only a narrow selection of bioweapons queries; that is "no longer certain... enough," given well-resourced malicious actors and models' growing real-world scientific ability. The worked example: predicting how a genetic modification affects adeno-associated virus (AAV) capsid assembly — Mythos-class models outperformed dedicated protein-language models using biological reasoning alone, without being trained for it (see Autonomous Scientific Discovery). Because the same skill that aids gene therapy could design dangerous viruses, Fable currently falls back to Opus 4.8 on most biology/chemistry requests — deliberately over-broad, to be narrowed later.
- Distillation. Requests flagged as attempts to distill Fable 5's capabilities into competing models (a known large-scale extraction threat, especially toward "authoritarian countries") fall back to Opus 4.8. The risk is indirect proliferation of near-frontier capability without the corresponding safeguards.
Robustness (red-teaming)#
The classifiers extend Anthropic's prior constitutional-classifiers line (see Agentic Prompt Injection) with broader coverage, and were stress-tested against jailbreaks:
- An external bug bounty produced no universal jailbreaks in over 1,000 hours of testing.
- External red-teaming orgs "failed to find any universal jailbreaks on long-form agentic tasks so far" — although the UK AISI made progress toward one within a brief initial window.
- Anthropic concedes it is "likely impossible to completely prevent universal jailbreaks"; the goal is to make any remaining ones "sufficiently slow and costly that we can detect and prevent them before they are used at scale" — a tedious-vs-impossible framing applied to the safeguard itself.
A universal jailbreak is defined as any prompt/script/harness that lets a user interact with the model "as if its safeguards were not present," as opposed to minor jailbreaks effective only in narrow contexts.
The 30-day retention policy#
Coupled to the safeguards: Anthropic now requires 30-day data retention for all Mythos-class traffic (first- and third-party, including business customers). The data is used only for safety — defending against complex/novel attacks (new jailbreaks, cross-request attacks) and reducing false positives — not for training, with logged human access and deletion after 30 days in almost all cases. A capability threshold thus changes not just the model's guardrails but the data-handling contract around it.
The fallback paradox (Opus 5, July 2026)#
The architecture carries forward to Opus 5 — same Fable-class classifier stack, same Opus 4.8 fallback target — and produces a result that inverts its own logic. Running the Automated Behavioral Audit against the full deployed system (model + Trust & Safety classifiers + fallback) rather than the raw model, Anthropic finds regressions on several alignment dimensions, including disallowed cyberoffense. The cause is not a safeguard failure: Opus 5 is more aligned than Opus 4.8 on nearly every metric, so falling back hands the request to a less aligned model.
Anthropic's argument that the system is still safer is a capability argument, not an alignment one: Opus 4.8 is "incapable of providing the same level of uplift," and at these low absolute scores the dimensions "largely measure the target's willingness, rather than severity of the uplift." That holds — but it means the fallback's safety case now rests entirely on the capability gap between the two models, and the gap is what shrinks with every release. When the fallback target is a generation behind on capability and two generations behind on alignment, "fall back rather than refuse" starts trading a small uplift reduction for a measurable willingness increase. The card's own gloss: "this highlights how improvements in alignment and safeguards can have surprising effects."
One quantitative note on false-positive rates, which the open question below asks about: on FrontierBench, Opus 5's classifiers flagged 5% of API calls across 4% of trials, against Fable 5's 42% of calls across 26% of trials — an order-of-magnitude reduction in fallback frequency on a science-and-engineering agentic benchmark, consistent with the deliberately over-broad bio classifier being narrowed.
Measured from outside: a competitor counts the fallbacks (July 2026)#
Every figure above is Anthropic's own. Moonshot AI's Kimi K3 card (2026-07-26, vendor-claim) supplies the first third-party counts, as incidental disclosure in its benchmark footnotes:
| Benchmark | Fable 5 fallback / refusal rate |
|---|---|
| SWE-Marathon (Claude Code harness) | fallbacks on 35% of tasks |
| Kimi Code Bench 2.0 (80 tasks, includes cyber/safety content) | 13 fallbacks + 1 refusal = 17.5% |
| Agents' Last Exam (leaderboard entry, xhigh) | 40% of tasks annotated as downgraded |
Two things make these worth recording. First, they are against the reporting party's interest — Moonshot explicitly notes the SWE-Marathon rate "may have negatively impacted [Fable 5's] measured performance," conceding a confound that flatters its own model. Second, they are broadly consistent with Anthropic's FrontierBench figure of 26% of trials and extend it: SWE-Marathon is ordinary long-horizon software engineering with no cyber or bio framing, and it produced the highest rate of the three. If that holds, the conservative tuning is not confined to science-and-engineering-adjacent work; it fires on plain agentic coding.
The card also reports refusals — not fallbacks — for the OpenAI models on the same 80-task set (GPT-5.6 Sol: 10 refusals via its "cyber guard"; GPT-5.5: 3). That is the fallback-not-refusal design working as intended, visible in a competitor's data: Anthropic's models are downgraded where OpenAI's simply decline, and only one of those two outcomes leaves a usable answer behind.
Caveats: these are counts from one vendor's evaluation runs, unaudited, with no per-task detail and no way to separate the bio classifier from the cyber or distillation ones. And a fallback rate measured on a benchmark harness is still a benchmark proxy for professional traffic — see Compute-Controlled Benchmarking for what else these footnotes do and don't control.
A workload abandoned over it (2026-07-24). Cline reports trying its autonomous harness-optimization campaign (Agent-Authored Harness Optimization) with Fable 5 as the leader model and giving up: "its AI safety filter kept downgrading the model to Opus-4.8." It reran the campaign on GPT-5.6-Sol instead, and notes separately that "its safety filter repeatedly blocked us from doing AI evals research." This is a passing remark in a blog post, not a measurement — no rate, no per-prompt detail, no way to tell which classifier fired — but it is a different kind of evidence from the counts above: not a percentage inside a scored benchmark run, but a real 17-hour engineering workload that a third party stopped attempting because of the fallback. The workload is ordinary agent-harness debugging with no cyber or bio framing; the plausible trigger is the campaign's subject matter (evaluation, benchmark scoring, agent self-modification) reading as adjacent to a gated domain. Worth recording precisely because the cost of a fallback that fires on a long-horizon autonomous run is not a lower score — it is the run being abandoned, which no benchmark table can show.
What the safeguard does to a comparison it isn't part of (July 2026)#
A government evaluator's methodology note makes the architecture above visible from an angle
Anthropic's own reporting cannot show it from.
UK AISI and US CAISI (AISI /
CAISI, 2026-07-23, empirical), comparing US frontier models against open-weight PRC
models on offensive cyber, state their convention plainly: "U.S. closed-weight models were
evaluated with system-level safeguards disabled to reduce refusals and enable measurement of maximal
capabilities. Publicly available versions of these models have these safeguards enabled."
That sentence is the fallback architecture's shadow. The reason a third-party cyber evaluation of an American frontier model has to disable safeguards is that with them on, the measurement is of the classifier, not the model — this page's own §1 records that in blocking mode "our classifiers prevent Fable from making any progress" on offensive cyber tasks. So a published US-versus-PRC cyber gap is necessarily a latent-capability gap: the number describes a configuration no general-access user can reach. Two consequences worth keeping:
- The safeguard makes its own subject unmeasurable from outside. Nobody without a de-safeguarded build can independently check any offensive-cyber claim about these models. The fallback design buys safety by making the capability unavailable, and third-party verifiability is priced into that trade.
- The de-safeguarded/as-shipped asymmetry is one-sided. Kimi K3 was evaluated as hosted, and AISI/CAISI report its safeguards did not prevent attempted exploit development — so one arm of the comparison is at maximal capability by design and the other is at maximal capability by default. The ranking of obtainable offensive-cyber capability may invert; see Open-Weight Elicitation Irreversibility.
Where it sits#
RSP determines which capabilities need gating (cyber, CB, AI-R&D, misalignment); this architecture is how the cyber/bio gate is implemented at inference for a generally-released model. It is the deployment-time complement to the training-time and policy-level brakes — and the operational answer to the question Mythos Preview left open: how do you ship Mythos-class capability to everyone without shipping the uplift?
The safeguard stack behind the gate (August 2026)#
Anthropic's August 2026 Risk Report documents the classifier system this page describes as a two-axis arrangement — robustness (how hard to jailbreak) and coverage (how much of the topic space is blocked) — applied at different levels to different models. That separation is the useful abstraction: they are independently tunable, they fail differently, and the report's two biggest CB findings land one on each axis.
Robustness levels.
- Level 1 — the design described in the February 2026 Risk Report, patched for specific known jailbreaks. Used on Opus 4 and 4.1 (both deprecated, expected fully unavailable later in 2026), and on one hard-to-update product surface for Sonnet 4.5/4.6 and Opus 4.5/4.6.
- Level 2 — the updated Constitutional Classifiers design (January 2026 paper). Same two-stage shape as Level 1 — a streaming classifier built on linear probes of model internals escalating to a more expensive fine-tuned-model second stage — but the block decision is a weighted combination of probe and classifier scores rather than the second stage alone.
- Level 3 — Level 2 with a lower blocking threshold, i.e. more conservative. Used on Opus 4.7, Opus 4.8, Sonnet 5, and all Mythos-class models.
Coverage moved separately: the classifier constitution was extended from CB-1 uses to a large (not comprehensive) set of CB-2 uses. Validation is worth recording as a fact about generalization — on a synthetic set built from 30 CB-2-but-not-CB-1 examples expanded through thousands of jailbreak-transformation compositions, the original CB-1 classifiers already flagged 97.5% of it, purely by generalization from earlier constitutional training. Fable 5 then goes further with a strictly wider coverage domain (see that page).
The bug bounty, priced. Anthropic pays up to $35,000 per novel universal jailbreak through its HackerOne program, on a curve that rewards non-universal findings too. Since March 1, 2026 it has paid $87,800 across 21 reports, validating 5 non-universal jailbreaks and 1 universal one — representing about 600 self-reported hours of red-teaming from submitters alone. The universal jailbreak applies only to Level 1 classifiers; Level 2's weighted two-stage design mitigated it without additional training. (A second universal-jailbreak bounty was paid and then withdrawn on inspection: the submission had gamed the automated bounty system's rubric rather than obtained real help from the model — Reward Hacking appearing in the safety program's own incentive design.)
Where the axes failed. The coverage axis held; the deployment of the whole stack did not. From May 2025 to April 2026, all human-feedback vendor traffic ran with blocking biological classifiers disabled by an internal-use flag that also suppressed classifier-hit logging — ~50,000 people, ~133M exchanges, on models including Mythos Preview. Reviewed after the fact and found clean, and Anthropic's conclusion is the general one: "the discovery of this gap… leads us to believe that there is an increased likelihood of other, similar issues unknown to us." Appendix 6.5 adds six smaller ones in the same shape — a probe threshold copied by hand from the previous classifier and left too high for five days; a streaming-classifier bug leaving ~40 median tokens of each exchange unscored for months; image data stripped from second-stage classifier input for ~two months; a customer's exemption inherited by ~4× the approved seats. A classifier's robustness level is a property of the classifier; whether it is running is a property of the deployment, and every incident in this report is on the second axis.
Connections#
-
Structured Safety Case (Claim Decomposition) — the argument these safeguards are the mitigation half of; the CB-1 rating rose because of a deployment gap in this stack, not a robustness failure
-
Continuous Self-Modification Under Review — the same lever pointed the other way. Here a vendor classifier routes a request down to a less capable model on a risk signal; there the concern is a self-modifying agent re-routing its own model slot up, which "can increase autonomous capability, alter refusal behavior, enlarge the prompt-injection surface, and change cost by orders of magnitude without changing the visible task interface." Ouroboros's mitigation is to make model routing an audited configuration change rather than an ordinary runtime choice — a config-layer analogue of the safeguard rather than a model-layer one
-
Agentic Prompt Injection — Fable's classifiers extend the constitutional-classifier line documented here; jailbreak-robustness is the shared adversarial frame
-
Claude Code Auto Mode — the same classifier-gating idea at the tool-call boundary; this page applies it at the query boundary, and swaps a weaker model rather than blocking
-
Responsible Scaling Policy Evaluations — the RSP decides what must be gated; this is the inference-time mechanism, and Mythos-class crossing the risk threshold is what forces it
-
LLM-Driven Vulnerability Research — the cyber capability the cyber classifier neutralizes; Fable blocks "any progress" on offensive cyber tasks
-
Autonomous Scientific Discovery — the bio capability the bio/chem classifier gates; the AAV dual-use example is the motivating case
-
Claude Fable 5 — the model that ships these safeguards on
-
Claude Mythos 5 — the model with these safeguards lifted; the contrast that defines the two SKUs
-
Claude Opus 4.8 — the fallback target; the "far better than refusal" experience rests on it being highly capable in its own right
-
Claude Opus 5 — the model that inverts the logic: falling back to Opus 4.8 makes the deployed system less aligned, leaving the safety case resting on the capability gap alone
-
Automated Behavioral Audit — the audit variant run with fallbacks enabled, which is how the regression was measured
-
Claude Sonnet 5 — a lower-risk point on the same safeguard spectrum: native low cyber capability (no deliberate train-down), inference-time detect-and-block at the Opus-4.7/4.8 strictness level, and no model-swap fallback — Anthropic judged the uplift risk too low to warrant Fable 5's broader classifier-plus-fallback regime
-
Impossible, Not Tedious (Design Test) — the safeguard's own success criterion: make jailbreaks slow/costly enough to catch before scaled use
-
Open-Weight Elicitation Irreversibility — this entire architecture presupposes a server the vendor controls; an open-weight release forfeits it, along with suspension and retention
-
Compute-Controlled Benchmarking — the footnotes that produced the outside fallback counts, and what they still fail to control for; a safeguard that fires on 35% of a benchmark is a confound the grid never displays
-
Kimi (Moonshot AI) — the competitor whose evaluation footnotes measure this architecture's firing rate from outside Anthropic
-
Cline — the outside party that abandoned a real long-horizon workload rather than absorb the downgrades; the anecdotal counterpart to Moonshot's counts
-
UK AI Security Institute / US Center for AI Standards and Innovation (CAISI) — the evaluators who have to switch this architecture off to measure the model underneath it, and who say so in the methodology note
-
Agent-Authored Harness Optimization — the campaign that was moved off Fable 5; a fallback firing mid-run on a 17-hour autonomous job costs the whole run, not a few points
-
Capability Gating Is Not Authorization — different sense of "capability" — do not conflate. Here, capability = a model's dangerous knowledge level, and the "gate" is a query-level classifier that routes risky prompts to a weaker model (fallback-not-refusal). There, capability = which tools are exposed to an agent, and the thesis is that gating capabilities is not authorizing calls (a tool-call-level per-argument-value check). Same word, orthogonal mechanisms — one routes models by query risk, the other authorizes tool-call arguments against operator policy
-
Balance-of-Power Superintelligence — the direct disagreement on this page's distillation gate: Zuckerberg asks that "you can learn from anything you can observe" be protected as an open-ecosystem principle, where this architecture classifies distillation as a threat class alongside cyber and bio. Not an empirical dispute — a dispute over whether model outputs are observable knowledge or a protected asset
Open Questions#
- The >95%/<5% figures are session-level; what's the false-positive rate for legitimate security researchers and biologists, whose benign queries are exactly the ones most likely to trip the conservative classifiers? Partially answered: on FrontierBench (74 hard science/engineering terminal tasks), Claude Opus 5's classifiers flagged 5% of API calls in 4% of trials where Fable 5's flagged 42% in 26% — so the over-broad tuning was costing roughly a quarter of trials on exactly this kind of legitimate technical work, and has been substantially narrowed. Still a benchmark proxy, not measured professional traffic. Further evidence (2026-07-30): a competitor's benchmark runs (Kimi K3 card) put Fable 5's fallback rate at 35% of SWE-Marathon tasks, 17.5% of Kimi Code Bench tasks and 40% "downgraded" on Agents' Last Exam — corroborating the order of magnitude from outside Anthropic, and locating it on plain software engineering rather than only on science-adjacent work. Still benchmarks, still not professional traffic.
- Fallback-not-refusal preserves UX but means the real general-access model for security/bio-adjacent work is Opus 4.8, not Fable — does that quietly cap Fable's value for whole professional segments until the trusted-access programs open? Partially answered (anecdote, 2026-07-24): Cline abandoned a 17-hour autonomous evals-research campaign on Fable 5 because the classifier "kept downgrading the model to Opus-4.8," and ran it on a competitor's model instead — the first instance in this corpus of the cap being paid as a lost workload rather than as a lower benchmark score, and from outside Anthropic. One vendor's passing remark with no rate attached; it establishes the failure mode exists in the wild, not its frequency.
- The UK AISI's "progress toward a universal jailbreak" is disclosed but not quantified — and the post-launch access suspension (see Claude Fable 5) raises the question of whether a safeguard failure forced it.
- Does swapping to a weaker model on flagged topics create an exploitable oracle (probe which queries trigger fallback to map the classifier's boundary)?
Sources#
- Claude Fable 5 and Claude Mythos 5 — §"Claude Fable 5's new safeguards" (safety classifiers; cyber/bio/distillation coverage; red-teaming; 30-day retention)
- Claude Opus 5 System Card — §6.4.7 (behavioral audit with Trust & Safety fallbacks enabled; the alignment regression and Anthropic's capability-gap rationale), §8.5 (classifier flag rates on FrontierBench). Parse hazard: this PDF's raw markdown shifts table rows — model names land inside value columns across the §4 safeguards tables (4.1.1.A, 4.2.B, 4.3.1.B, 4.3.2.A, 4.4.2.B, 4.4.3.B), the §5.1 agentic-safety tables (5.1.1.A–5.1.3.A) and Table 8.13.6.A, so a row read literally can hand one model's score to another. Figures quoted here were reconciled against the PDF on 2026-08-03 and are prose- or figure-corroborated; never quote a table row from the raw markdown unchecked
- Kimi K3 Model Card — §3 footnotes 2 and 3 (2026-07-26,
vendor-claim): Fable 5 fallback fractions on SWE-Marathon, Kimi Code Bench 2.0 and Agents' Last Exam, plus refusal counts for GPT-5.6 Sol and GPT-5.5 on the same task set - UK AISI / CAISI Preliminary Assessment of Kimi K3's Cyber Capabilities — UK AISI / US CAISI, 2026-07-23 (
empirical, joint government evaluation): the "Detailed Results" methodology paragraph stating that US closed-weight models were evaluated with system-level safeguards disabled to measure maximal capabilities while publicly available versions have them enabled, and the finding that Kimi K3's own safeguards did not prevent attempted exploit development. Limit: the de-safeguarded US models are never individually named, so it cannot be established which of them carry this page's classifier stack - Risk Report: August 2026 (Redacted) — Anthropic, Risk Report: August 2026 (Redacted), RSP v3.4 (
empiricalin method, first-party in provenance). §4.5/Table 4.5.A (the robustness/coverage/exemptions axes and the per-model assignment), §4.5.1 (Level 1/2/3 definitions), §4.5.2.1 (CB-2 coverage extension and the 97.5% generalization result), §4.5.3.1 (bug bounty economics: $35k cap, $87,800 paid since 2026-03-01, 21 reports / 5 non-universal / 1 universal, ~600 hours, and the rubric-gamed submission), §4.5.8.2.2 (the human-feedback classifier gap), §6.5 (the six minor incidents). Table 4.5.A is split across three docling blocks and read with §4.5.1's prose, which restates the level assignments; no row is quoted that the prose does not corroborate. Parse note: ingest verifywarnontable-collapse(5 cells), all confirmed false positives;table-shiftclean; canary-recall 19/20
Cited by 27
- Claude Fable 5×4
Claude Fable 5 is Anthropic's first generally-available Mythos-class model (launched June 2026) — a…
- Open-Weight Elicitation Irreversibility×4
Capability Gated Model Fallback — Fable 5's classifiers route cyber/bio/distillation queries to a…
- Claude Mythos 5×3
Claude Mythos 5 is the safeguards-lifted form of Claude Fable 5 — "the same underlying model... but…
- Claude Opus 4.8×3
4.8's second life continues and gets stranger: it remains the fallback target under Opus 5's Trust…
- LLM-Driven Vulnerability Research×3
Capability Gated Model Fallback — the cyber classifier + Opus-4.8 fallback that neutralizes Fable…
- Open Questions Backlog×3
Capability Gated Model Fallback: The >95%/<5% figures are session-level; what's the false-positive…
- Anthropic×2
Capability Gated Model Fallback — Anthropic's general-release safeguard architecture (classifiers +…
- Automated Behavioral Audit×2
A new variant runs the whole audit with Trust & Safety fallbacks enabled, measuring the deployed…
- Autonomous Scientific Discovery×2
Capability Gated Model Fallback — the dual-use flip side; the AAV result is the bio classifier's…
- Balance-of-Power Superintelligence×2
Capability Gated Model Fallback — the live mitigation the distillation argument lands against: one…
- Claude Opus 5×2
Capability Gated Model Fallback — the fallback architecture that now makes the deployed system…
- Claude Sonnet 5×2
This places Sonnet 5 as a distinct point on the safeguard spectrum mapped in Capability Gated Model…
- Cline×2
Cline attempted the same autonomous campaign with Claude Fable 5 as leader model and abandoned it:…
- Compute-Controlled Benchmarking×2
There is a second finding here that belongs to safety rather than evaluation: those fallback…
- The Configuration Gap: What an Assurance Argument Measures vs What It Covers×2
Capability Gated Model Fallback — the robustness × coverage two-axis frame; the HackerOne bounty…
- Continuous Self-Modification Under Review×2
Capability Gated Model Fallback — the mirror risk: an agent that can re-route its own model slot…
- Mythos Model×2
Fable 5 = a Mythos-class model "made safe for general use" via classifiers that fall back to Opus…
- Responsible Scaling Policy Evaluations×2
The mitigation shifts from gating to deployed safeguards. Where Mythos Preview was simply withheld…
- UK AI Security Institute×2
Capability Gated Model Fallback / Llm Driven Vulnerability Research / Claude Fable 5 — its partial…
- Agent-Authored Harness Optimization
Capability Gated Model Fallback — the abandoned arm of the experiment: Cline dropped Fable 5 as…
- Agentic Prompt Injection
Capability Gated Model Fallback — Fable 5's safety classifiers extend this page's…
- Capability Gating Is Not Authorization
Capability Gated Model Fallback — different sense of "capability" — do not conflate. There,…
- Claude Code Auto Mode
Capability Gated Model Fallback — the same classifier-gating idea at the query boundary: Fable 5…
- Kimi (Moonshot AI)
Capability Gated Model Fallback — the card is the first third-party measurement of how often Fable…
- Superintelligence Trajectory
Capability Gated Model Fallback — Fable 5's safeguard architecture: classifiers detect cyber /…
- Reward Hacking
Capability Gated Model Fallback — reward hacking inside the safety program's own incentives: a…
- Structured Safety Case (Claim Decomposition)
Capability Gated Model Fallback — the mitigation stack the CB half of the argument rests on, and…
Related articles
- Responsible Scaling Policy Evaluations
Anthropic's RSP gates deployment on pre-release capability evaluations in CBRN, automated AI R&D, and high-stakes misal…
- Claude Fable 5
Anthropic's first generally-available Mythos-class model (June 2026) — state-of-the-art on nearly all benchmarks; the s…
- Claude Opus 5
Anthropic's Opus-class release of July 2026; matches Mythos 5 on capability without advancing the frontier, is the best…
- Claude Mythos 5
The safeguards-lifted form of Claude Fable 5 (June 2026): same underlying Mythos-class model, deployed through Project…
- Claude Opus 4.8
Anthropic's most capable general-access model as of May 2026, since superseded by Fable 5 and Opus 5 and now the fallba…