Sources#
- A Closed-Form Estimator and Diagnostic Battery for Anchor-Judge Error Correlation, Under a Single-Common-Factor Model
- A Statistical Framework for Auditing Behavioral Dependence and Induced Bias in LLM Judges
- Agreement Overstates Evidence: Error Dependence in LLM Judge Consensus
- CS329A Self-Improving AI Agents — Part 3: Robust Verification
- Inside the JEV Ecosystem: 13 Answer Verifiers on One Test Set
- Nine Judges, Two Effective Votes: Correlated Errors Undermine LLM Evaluation Panels
Summary#
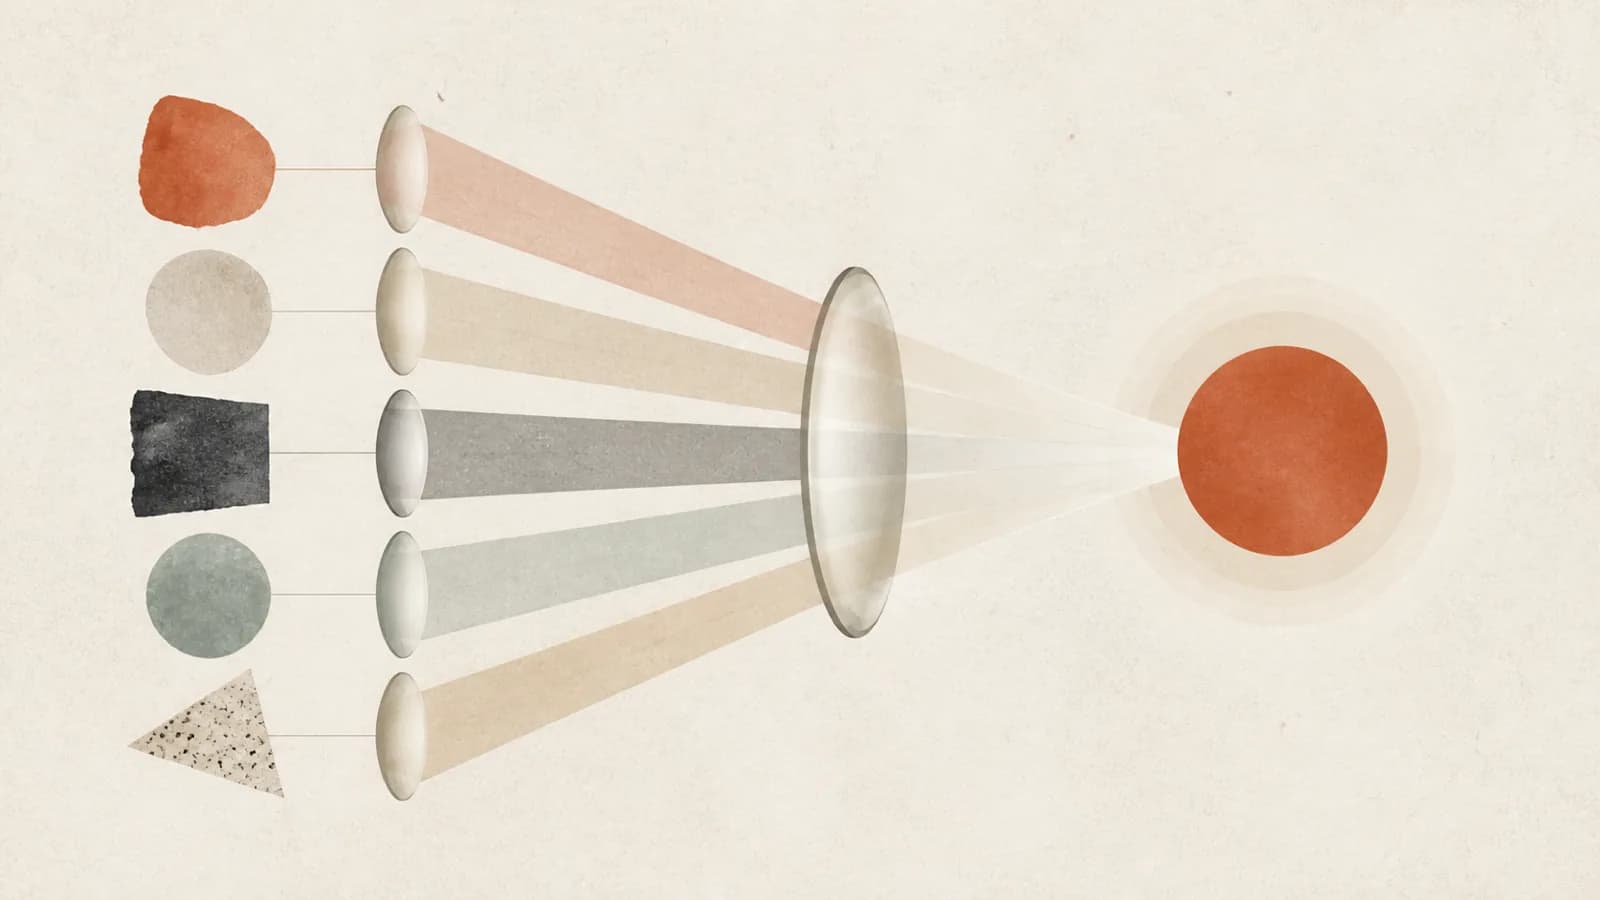
Every other route to closing the generation–verification gap trains a better verifier. Weaver — Shrinking the Generation-Verification Gap with Weak Verifiers, from Azalia Mirhoseini's Stanford lab, taught in CS329A lecture 3 (CS329A Self-Improving AI Agents — Part 3: Robust Verification, delivered 2025-09-29, published 2026-08-03, practitioner-opinion) — spends inference compute instead: take the verifiers that already exist, none of them good enough alone, and combine them into one that is.
"Weak" is a claim about the world, not about the selection. Mirhoseini is explicit: "we didn't purposefully choose bad verifiers — these are the best verifiers that are out there," and the weakness is simply that no verifier is perfect. The formal property required is only that each verifier's score correlates with true correctness while being individually imperfect. Three classes go in the pool: outcome reward models, process reward models (both on Process vs Outcome Reward Models), and LLM judges — the last being any prompted model that can be shown an answer and asked whether it is right, optionally with rubrics or tools.
This page carries the method, the reported numbers, and the contradiction: Weaver's derivation rests on verifier independence, and the 2026 empirical sources on this wiki measure that independence and find it absent, in the direction that costs it. The resolution is scoping rather than supersession, and it is developed below.
Figures are read off slides in a YouTube auto-caption transcript, the paper is not in raw/, and the lecturer is the senior author. Treat every number as approximate and late-2025.
The result that motivates the design#
Before any machinery: rank the available verifiers by quality and ensemble the top 1, top 5, top 10 across four benchmarks. More verifiers helps — but not monotonically. What always helped was learning a weight per verifier from a labelled set, using methods the lecture calls deliberately simple: naive Bayes or logistic regression, one scalar per verifier, fit on a training split and applied to held-out test data.
Hold onto the non-monotonicity. It is the first observable in the lecture that the independence assumption below is not true.
Score → weight → select#
Weaver's pipeline, in the lecture's own three words:
- Score. Run every verifier over every candidate solution; normalize the scores onto a common scale (verifiers emit 0/1, log-probabilities of correctness, and other things that are not comparable as given).
- Filter. Drop verifiers that score badly against a very limited labelled set. Mirhoseini flags this as load-bearing: "we have noticed that this is a very important step — your verifiers should be above a certain quality to even be let in the pool." A bad verifier does not average out; it has to be excluded.
- Weight and combine. Estimate each surviving verifier's accuracy by weak supervision with very little labelled data, and combine the scores under those weights.
The weak-supervision lineage is named: Snorkel (Alex Ratner et al.) and the related Stanford weak-to-strong line.
The setup and the assumption#
n queries × k solutions each × m verifiers = n·k·m labels. The target is P(correct(i,j) = 1 | all m verifier labels). Two equations do the work — a factorization that requires every pair of verifiers to be conditionally independent, and Bayes' rule, which assumes nothing — and together they yield an optimization whose solution is the per-verifier weights.
The assumption stated plainly, because everything downstream turns on it:
the assumption in Weaver is that each verifier captures an independent aspect of the correctness.
Mirhoseini gives the intuition immediately, and it is the right intuition: if every verifier agrees on every sample you learn nothing from having many. The signal lives in the pattern of agreement and disagreement across the pool. That is exactly why the assumption is load-bearing rather than a convenience — the method's value is the independence it posits.
What it reports#
- Gains concentrate on hard benchmarks. GPQA Diamond, MATH and MMLU-Pro, where the single-verifier baseline is already low, show the largest boost over a naive ensemble. Easy benchmarks show little.
- Four arms, ordered. A pass@k oracle (dashed, the unreachable ceiling); supervised Weaver (a large labelled set for the weights); unsupervised Weaver (1% of each dataset's training labels — the name is the lecture's, and the 1% is not zero); naive ensemble (plain averaging over the filtered pool). All four sit significantly above majority voting and multi-agent verification, where MAV is prompting LLMs to score a response on several rubric-style aspects — and MAV lands below majority voting on two of the datasets, which is a quiet negative result for rubric-prompted judge panels as a verification method.
- The headline movement: from "slightly over 40%" to "over 70%" on the hard problems, which she notes matches o3-mini.
- Model-class closure, on solution accuracy rather than coverage. This is the framing she stresses, since the previous lecture's results were all coverage:
- Generator Llama 3.1 8B Instruct with a verifier pool of 8B-and-below models → ~70% average, roughly what majority voting with 70B-class models achieves.
- Generator and verifiers at the 70B class → 86.2% average, "very comparable" to o3-mini, a proprietary model of a different class.
The claim is that inference-time verification buys you roughly one model class, using only open weights — which is the same trade The Open-Weight Frontier Gap tracks from the model side, arrived at by spending inference compute rather than training compute.
Distillation: the cost objection, answered#
Running m verifiers over k samples per query is expensive, and the expense scales with both. The follow-up work trains Weaver once and distills the whole ensemble into a single small scorer — as small as ~400M parameters against an original pool in the 70B range — reportedly retaining ~97% of the ensemble's accuracy at 99%+ less test-time compute. Distilled and original checkpoints are open-sourced; Mirhoseini offers them to the class as project infrastructure.
The efficiency curve (success rate against total inference FLOPs) has the distilled model far left of everything else — but the part worth noting is that the undistilled Weaver also becomes more FLOP-efficient than naive ensembling and majority voting at high accuracy levels, because those methods cannot reach those levels at any budget. Efficiency comparisons between methods with different ceilings only make sense per accuracy level.
The contradiction: independence is the assumption the wiki has measured#
Weaver's derivation needs conditionally independent verifiers. Two 2026 empirical sources here measure the quantity directly, and both find strong dependence.
- Yang et al. (2026) estimate intra-class error correlation ρ from judge vote matrices under ordinary pairwise grading with nothing optimizing against the judges: ρ = 0.944–0.972 for Qwen3 homogeneous juries and 0.664–0.706 for MiniMax ones — both within-family figures, for two different families. Heterogeneous juries also underperform Poisson-binomial independence predictions — mixing model families under a shared prompt does not restore independent errors. Five jurors buy 0.463 → 0.482 on LLMBar. Their prescription is to report ρ alongside K, never K alone.
- Zhou (2026)'s Proposition 2 gives the analytic form: every monotone aggregation rule over judges thresholding a shared latent plausibility axis collapses to a threshold on that axis, so adding judges cannot reject a region all of them accept. Measured pairwise acceptance correlation across three judge families: φ = 0.29–0.38, and a strictest-unanimous three-family rule still passes 55% of manufactured wrong answers.
How this resolves — scoping, not supersession. Weaver's reported gains are not in dispute; the mechanism it credits them to is what the later evidence indicts. Four distinctions decide how much of the method survives:
- The pool is heterogeneous by kind, not just by weights. Yang and Zhou both measure LLM judges — models prompted to grade text. Weaver's pool mixes trained ORMs and PRMs (which score against a learned correctness head fitted on ground-truth-matched labels) with judges. A reward model trained on outcome-matched data and a chat model prompted to grade share far less machinery than two chat judges do. Nothing here measures error correlation across that mix, and it is the one place independence is most plausible.
- Weaver is anchored to ground truth; a judge council is not. The filtering step and the weight fit both consume real labels — even the "unsupervised" arm uses 1%. Zhou's failure mode is specifically the reference-free judge, and the fix he identifies is a verdict grounded in something the judge did not generate. Weaver has such a grounding, thinly.
- Weaver runs as a static selector, not a reward. Zhou's collapse (discrimination 0.31 → 0.09) is measured under optimization pressure. Weaver as taught selects among fixed candidates with nothing training against it — Yang's regime, where judges retain usable discrimination, not Zhou's. Anyone using Weaver as an RL reward is in the other regime and inherits the collapse, and the lecture makes no such distinction.
- The lecture's own data already shows the cost. Ensembling top-1 → top-5 → top-10 helps non-monotonically, which is what correlated errors predict and independence does not. Weaver's answer — learn weights instead of averaging — is a mitigation for correlated verifiers, not evidence that they are uncorrelated. The method is better than its stated justification.
The honest summary: the recipe's ground-truth-anchored parts (filter the pool, fit weights on a small labelled set) are the parts the later evidence does not touch; the independence story it tells about why more verifiers help is one the later evidence contradicts. Multi-Agent Collective Intelligence carries the general form of the same mechanism from control theory — width averages only the noise that is independent per agent, so structure shared across the population is a floor that no population size lowers.
And a second, smaller tension inside the same lecture. Mirhoseini also says models "like their own generations and their own way of interpreting results much better" than another family's, and that she knows of no study on whether generator and verifier should share an architecture family (Same-Model Review Blindness). If verifiers of one family systematically agree, that is the dependence above; if a generator's own family systematically over-credits it, that is a directional bias no amount of weighting removes. Weaver's cross-lab pool is the right instinct against both, argued for on grounds the lecture does not connect to either observation.
Pricing the dependence: a closed form, and the identification wall it hits (September 2026)#
This page's first open question asks what a ρ-corrected aggregation would predict against what Weaver's weight-fitting recovers. Sunkavalli (A Closed-Form Estimator and Diagnostic Battery for Anchor-Judge Error Correlation, arXiv 2609.08826, 2026-09-08, single independent author, empirical — a tier that covers the simulations and the diagnostics and covers nothing about a real panel, see Sources) supplies the first instrument in the corpus whose estimand is the dependence itself rather than a dependence-corrected accuracy. What it mostly delivers to this page is not a number to plug in but a budget: the conditions under which the pricing exercise is possible at all, most of which a Weaver-shaped pool does not meet.
Why a pool cannot price itself. Model each judge as J_j = t + c + e_j — one latent quality t, one common-mode error c shared by every judge, an idiosyncratic residual e_j — and the observable off-diagonal judge covariance is
K = Cov(J_i, J_j)_{i≠j} = σ_t² + σ_c²
signal plus shared error, and the panel cannot split them at any size. Judges agreeing tells you nothing about why they agree; that is the same fact Yang's ρ reports from the vote-matrix side, stated as an identification problem instead of a measurement. Splitting K requires an external reference set — an anchor — and the standard move then assumes the anchor is clean: its error uncorrelated with c. The paper's estimand is exactly that assumption's residual, one per anchor: with anchors A_k = t + (β_k/σ_c²)·c + u_k, β_k:= Cov(A_k, c) and the contamination ρ_k:= β_k/(σ_{a_k} σ_c), where σ_{a_k}² is anchor k's total error variance and ρ_k = 0 is the clean anchor.
Theorem 1. With p ≥ 2 judges and m ≥ 2 anchors, and observable moments M_k = Cov(J̄, A_k), P_kℓ = Cov(A_k, A_ℓ), all of σ_t², σ_c² and every ρ_k are point-identified in closed form whenever (K + P₁₂) − (M₁ + M₂) ≠ 0:
σ_t² = (K·P₁₂ − M₁M₂) / ((K + P₁₂) − (M₁ + M₂))
σ_c² = K − σ_t², β_k = M_k − σ_t², ρ_k = β_k/(σ_{a_k} σ_c)
No clean-anchor and no anchor-difference assumption is required. The judge panel is what supplies the identification — at p < 2 there is no off-diagonal, K is undefined, and nothing is identified. Identifiability itself is inherited from the multitrait-multimethod method-factor literature (Campbell & Fiske 1959; Eid's CT-C(M−1) reference-method design) and the paper says so outright; the closed form, the exact failure boundary, the violation taxonomy and the calibrated battery are the contribution.
The designated-clean-anchor failure, made quantitative. This is the result that transfers cleanly to any verification stack with a trusted reference. A CT-C(M−1)-style estimator that designates one anchor clean recovers the companion anchor's ρ₂ correctly only while that designation is true, and degrades linearly as the trusted anchor's own contamination grows: ρ̂₂ = 0.502, 0.411, 0.270, −0.002 at true ρ₁ = 0, 0.2, 0.4, 0.6 — reporting a heavily contaminated anchor as fully clean at the end of that range — while the closed form stays at 0.501 throughout (true ρ₂ = 0.5). A wrong trust assumption does not produce a noisy answer; it produces a confident zero.
Assumption 2 is Weaver's assumption, named and dissected#
The paper isolates Assumption 2 (conditional judge-residual independence) — "all shared judge variation is carried by the single common-mode factor c" — as the empirically fragile one, and its stated failure case is this page's pool verbatim: "LLM judges built on a shared base model, prompt template, or preference-tuning lineage plausibly share residual correlation beyond c." Three things follow, and they are the sharpest thing this source does for Weaver.
- The bias direction is a false "clean". With at least one genuinely clean anchor the effect is pure attenuation,
|ρ̂_k| < |ρ_k|. With both anchors contaminated it is configuration-dependent: attenuation in the moderate regime (a uniform judge residual of strength 0.6 drivesρ̂₂0.701 → 0.565 while inflatingσ̂_c²0.80 → 1.13), but inflation past|ρ| = 1near the identification boundary. So the typical error is the reassuring one. - The dispersion test is structurally blind to it. Because the residual loads uniformly across judges, Test A (below) cannot see it, and the over-identification test responds only weakly at realistic scale — judge-side power 0.06 / 0.16 / 0.99 at N = 500 / 2000 / 10⁴ at residual strength 0.6, against 0.99 at N = 2000 for its anchor-side target. At
N = 500, the scale of most eval sets, the test's power equals its own false-positive rate: it is not measuring anything. - Family blocking is the one operational remedy, and it runs on metadata. Model the residual as family-level,
J_j = t + c + f_{b(j)} + e_j. Then cross-family judge covariances equalσ_t² + σ_c²exactly — the residual cancels — so computingKfrom cross-family pairs only restores the closed form unchanged, and the within-minus-cross gapK_within − K_cross = σ_f²estimates the lineage residual directly, giving a third diagnostic (Test C) from judge lineage metadata alone, at any anchor count. It needs ≥ 2 families with at least one family holding ≥ 2 judges (sop ≥ 3), no extra anchors and no over-identification machinery. In simulation (six judges, three families, N = 4000) the naive estimator drifts toward "clean" as the family residual grows (ρ̂₂0.697 → 0.650 at residual s.d. 0.7) while the blocked estimator holds at 0.696–0.697; over 100 replicates per cell Test C flags 4/100 null datasets and 100/100 at every tested strength, recoveringσ_f²to the second decimal (0.088 / 0.248 / 0.488 against design values 0.3² / 0.5² / 0.7²).
Family blocking is the estimator-side form of the composition rule LLM-Judge Validation reaches from measurement: add a judge from outside the lineage and watch the dispersion. Here the cross-lineage pairs are not a robustness check — they are the only covariances that are clean by construction, and the within-family pairs are the contaminated ones. Mirhoseini's cross-lab pool is, on this account, load-bearing rather than good hygiene, and it earns a second justification the lecture does not give it: a Weaver pool spanning ≥ 2 lineages is the minimum configuration under which its own dependence is even estimable.
The battery, and the three walls behind it#
Because the single-common-factor assumption is untestable, the estimator ships gated behind a null-calibrated three-test battery — Test A, the coefficient of variation of the off-diagonal judge covariances (needs p ≥ 3; under the model they are all equal); Test B, ≥ 3-anchor over-identification on the spread of σ̂_t² across anchor pairs, which fires precisely where A is blind; and Test C, the family-block test above. Thresholds sit at the 95th percentile of each statistic's simulated null, giving a 5% false-positive rate by construction at every N (a correct-model Gaussian property — heavy tails inflate Test A to 0.083). Power at second-factor strength 0.4 / 0.6 (Table 3, reconciled against pdftotext): Test A 0.23 / 0.91 at N = 500, 0.93 / 1.00 at 2000, 1.00 / 1.00 at 10⁴; Test B 0.50 / 0.99, 0.99 / 1.00, 1.00 / 1.00. At loading spread 0.2 Test A's power is 0.04 at N = 500 and 0.11 at N = 2000 — at or below its own false-positive rate, so mild violations at realistic N are invisible. Inference is a 300-resample item bootstrap with measured coverage 0.953 at both N = 500 (width 0.244) and N = 2000 (width 0.118), plus a weak-identification screen T = |d̂en|/SD_boot(d̂en) < 4 in the spirit of a weak-instrument first stage.
Three walls stand behind all of that, and each one bites a Weaver-shaped pool harder than it bites the paper's own design.
- The panel-wide residual is undetectable, and it is the LLM-judge default. Family blocking removes a family-level residual. What survives is a residual shared by every judge — "a shared prompt template affecting every judge" — which no within-panel statistic can separate from the common mode, because it is observationally the common mode. The paper's own instruction is blunt: "a panel generated under a shared prompting protocol or template induces exactly this undetectable panel-wide case, so on such panels the estimator should not be used at all, whatever the diagnostics say." Weaver scores every candidate with every verifier under one harness; so does every judge panel on this wiki.
- All-ordinal scores identify nothing. With judges and anchors ordinal, the identifiable information is the polychoric correlation structure, thresholds absorb every latent location and scale, and a Jacobian-rank/null-space analysis shows
ρ_kis not identified at any number of anchors — verified numerically atm ∈ {2, 3, 4, 6}, with explicit equivalent parameterisations carryingρ₁ = 0.30andρ₁ = 0.80on identical observed correlations. More ordinal anchors do not help (each brings its own unknown scale), and a known-clean anchor does not restore it either. Identification returns only with ordinal judges plus≥ 3continuous-scored anchors, where a polychoric/polyserial + anchor-tetrad estimator recovers trueρ = (0.3, 0.7, 0.5)as(0.282 ± 0.129, 0.670 ± 0.078, 0.484 ± 0.103)at N = 4000 — at roughly an order of magnitude more variance than the continuous case at the same N. Since LLM judges overwhelmingly emit Likert scores, the standard configuration sits on the wrong side of this line. - A shared bias shaped exactly like quality is credited as quality. Proposition 1: add a second common factor loading
gon every judge andhon every anchor; wheng = hthere is an observationally equivalent single-factor model withβ′_k = β_k,σ_c²′ = σ_c²andσ_t²′ = σ_t² + g²σ_d². So a uniformly loaded second factor leavesρ_kunbiased — and the paper refuses the comfortable reading: "harmless" here means reparameterisest, not detected and corrected. A genuine shared bias of that symmetric shape is silently folded into the quality variance with no warning, and anyone usingσ̂_t²itself (a signal-to-noise assessment, say) inherits it. Only asymmetric loadings biasρ_k, and even then the bias is non-monotone in the asymmetry and changes sign:ρ̂₂ = 0.701, 0.761, 0.780, 0.769, 0.565at|g − h| = 0, 0.10, 0.20, 0.30, 0.60against true 0.7. Asymmetry tells you the estimate is biased; it does not tell you the direction or the size.
Status: a correct tool with no validated application#
This must travel with every number above. The estimator has never been validly applied to a real panel, and the paper's own Section 8 says so. Both real panels tested were rejected by the adequacy pre-test:
- HANNA (Chhun et al. 2022 story-evaluation benchmark; 431 stories, coherence 1–5, three human raters with extreme marginals — one places 62% of mass on category 5, another 41% on category 1). Test A statistic 0.589 against a matched-null 95th-percentile threshold of 0.247,
p < 0.0005. Real human raters violate the equal-loading structure. - A six-provider LLM judge panel (Amazon Nova Lite, Llama-3-70B, Mixtral-8x7B, GPT-OSS-120B, Qwen3-Next-80B, DeepSeek-V3.2; temperature 0, 499 complete-case items from a keyed GSM8K/SciQ pool, 6,000 calls / 5,996 parsed verdicts, checksummed and shipped). Test A statistic 0.175 against a matched-null threshold of 0.064. The mechanism is measurable and damning for the unit-loading model: the judges' quality loadings span 0.324–0.870 where Assumption 1 fixes them at 1. Run in defiance of the pre-test, the estimator returns (0.887, 0.960, 1.026) against injected
(0.0, 0.4, 0.7)— the closed form is not range-restricted, and|ρ̂| > 1is itself the misspecification signal.
The paper's honest framing is that the diagnostics are validated on real data in the rejecting direction only — specificity on a real adequate panel is untested because no such panel exists to test on. After oracle per-judge loading calibration (dividing each judge by its loading on the known quality construct, which conditions on the very quantity the method exists to estimate) recovery becomes (+0.024, +0.268, +0.558) against injected (0.0, 0.4, 0.7) — but the calibrated panel still fails Test A (0.343 vs 0.064), the anchors were synthetic, and the authors label the whole exercise a robustness observation rather than a validation. And when Test A does fire, the natural fallback fails too: a free-loading CFA fit on that six-judge panel is weakly identified (non-positive-definite information matrix) and does not recover the injection.
Two smaller results are worth keeping because they close off cheap objections. Maximum likelihood buys nothing here: on identical data the closed form and full-information ML in a standard SEM package are statistically indistinguishable at mid parameters (ρ̂₂ = 0.704 ± 0.016 both) and near the boundary (0.517 ± 0.265 vs 0.520 ± 0.237), and under a misspecified shared judge residual of strength 0.5 both are biased almost identically (0.585 vs 0.597 against true 0.7) — an optimizer confers no robustness to the violations that matter. And identification has an exact boundary: the denominator of Theorem 1 equals (σ_c² − β₁)(σ_c² − β₂)/σ_c², so it fails exactly at β_k = σ_c² (measure zero) inside a positive-measure weak neighbourhood where variance blows up fifteen-fold (ρ̂₁ = 0.955 ± 0.061 at true 0.99, against ± 0.004 at 0.90) — which is why the weak-ID screen exists, firing on 0% of datasets at mid parameters, 46% at ρ₁ = 0.90 and 100% at ρ₁ = 0.97.
What this leaves for Weaver. Not a correction to its numbers — nothing here re-scores an ensemble. Three things do transfer. The filter-and-weight steps consume real labels, and those labels are an anchor: if they were produced by annotators or a reference model sharing the pool's biases, the fitted weights inherit a contamination this literature says is measurable in principle and, on Weaver's configuration, not measurable in practice. The designated-clean result says the failure would be silent and confidently zero rather than noisy. And the panel-wide-residual verdict is the harshest reading available of a shared harness: on a pool scored under one prompting protocol, the shared-error term and the quality term are not separable by any within-pool statistic, so "how much of the gain survives once the dependence is priced" may not have a within-pool answer at all.
Someone ran the pricing exercise, and the price was 0.1 points (September 2026)#
This page's first open question asks what survives once the dependence is priced. Kuai et al. (arXiv 2604.07650, COLM 2026, empirical; full treatment on Cross-Model Error Entanglement) are the first in the corpus to build the de-entangled aggregator and report it against the right baseline — and the result is a warning about the premise rather than about the method.
The construction is Weaver's weight fit with two dependence penalties bolted on. Each verifier J_m gets a competence score q_m estimated on a calibration set — this page's step 3 — and then two exponential penalties:
w_m^(S) ∝ q_m^κ · exp(−η₁ R_m − η₂ T_m^(S))
where R_m is verifier m's mean entanglement with the rest of the pool (the redundancy Mirhoseini's non-monotonic top-1/5/10 curve is the symptom of) and T_m^(S) is its entanglement with the target model being judged (the lineage effect Same-Model Review Blindness measures). Entanglement is E(i,j) = λ·BEI + (1−λ)·CIG, estimated on a separate benchmark where ground truth exists. All four parameters — λ, κ, η₁, η₂ — are fitted by cross-entropy on a 500-question calibration split and frozen before a 500-question held-out split, which is more discipline than this page's own source applies.
And the increment over competence alone is inside the noise. On MMLU-Pro with three verifiers:
| Aggregation | Acc | F1 | Precision |
|---|---|---|---|
| Majority vote | 0.847 | 0.901 | 0.870 |
| Accuracy-based reweight (≈ this page's step 3 alone) | 0.881 | 0.919 | 0.891 |
| Entanglement-based reweight | 0.882 | 0.922 | 0.896 |
The paper's abstract reports "3.5 and 2.6 percentage-point gains in accuracy and precision… over majority voting," which is true and is the wrong comparison: competence weighting alone delivers +3.4 of the +3.5. Pricing the dependence adds +0.1pp accuracy, +0.3pp F1, +0.5pp precision on 500 held-out questions, where one point of accuracy is roughly one standard error. Their Figure 3 shows the mechanism: the calibrated weights are dominated by competence (GPT-5 near 0.42–0.50 across every target, GPT-4o-mini near 0.25) and barely move as the target changes.
What that does and does not settle for this page. Three scope limits keep it from being a verdict. The pool is three verifiers, so R_m averages over two others and the redundancy penalty has almost nothing to discriminate — this is the least favourable configuration for the method, not a representative one. The verifiers are prompted judges only, not Weaver's ORM/PRM/judge mix, so the page's "dependence across kinds of verifier" question is untouched. And the entanglement is estimated on the models' answering behaviour, then used as a proxy for their verifying behaviour, a step nothing in the paper validates.
Within those limits the reading is still uncomfortable, and it is the one this page should carry: the corpus's first attempt to convert measured dependence into a better aggregator recovers almost nothing that a quality floor and a competence weight do not already recover. That is consistent with the resolution argued above — Weaver's ground-truth-anchored steps are the parts that work and the independence story is the part that does not — and it puts the burden on anyone claiming the dependence is worth correcting to show the gain rising with pool size. The counter-reading, which the same table supports, is that both reweightings clear majority voting by 3.4–3.5 points, so the filter-and-weight half of this page's recipe reproduces on a third party's pool with no Weaver machinery at all.
The other half of the pricing exercise: the aggregators themselves, benchmarked against the ceiling (2026-09-22)#
The section above prices one new aggregation rule against a competence-only baseline and gets +0.1pp. Kohli (Apple, arXiv 2605.29800, empirical; full treatment on Cross-Model Error Entanglement) runs the complementary experiment: take the established aggregation rules, hand two of them oracle access to the gold labels, and measure them not against each other but against what independent voting would have achieved — a Condorcet null with per-judge, per-difficulty-bin confusion matrices and 10,000 Monte Carlo draws per item.
That ceiling is what this page has never had. Weaver's gains are reported against majority voting and against a single verifier; neither says how much of the available signal the weighting recovered. Kohli's does. On a 9-judge, 7-family panel with n_eff = 2.18 and a 22.0pp Condorcet gap on MNLI (accuracy in %, Tables 5 and 11, reconciled):
| Method | Oracle labels? | MNLI | SNLI | AlphaNLI | RewardBench |
|---|---|---|---|---|---|
| Majority vote | no | 72.0 | 77.7 | 88.7 | 92.7 |
| Dawid–Skene EM | no | 70.7 | 77.6 | 89.5 | 92.7 |
| Accuracy-weighted (5-fold CV) | yes | 72.2 | 77.7 | 88.7 | 92.7 |
| Phi-optimal / Markowitz (5-fold CV) | yes | 72.4 | 78.4 | 86.2 | 94.1 |
| Best individual judge | — | 71.8 | 84.2 | 91.2 | 95.5 |
| Condorcet prediction (independent) | — | 94.0 | 91.7 | 96.3 | 99.5 |
Four readings matter here, and three of them are about Weaver's own design rather than Kohli's panel.
- Accuracy-weighted voting is Weaver's filter-and-weight step in its simplest honest form, and with oracle labels and cross-validation it closes under 1% of the MNLI gap. The stable oracle methods close at most 11% on any of the four datasets.
- Phi-optimal (Markowitz) weighting is the "price the dependence" move done directly — invert the pairwise phi matrix to minimise correlated error, exactly the intuition behind weighting a redundant pool down. It is the best method on MNLI (72.4) and on RewardBench (94.1, closing 20.6% of that gap) and it is worse than plain majority voting on AlphaNLI (86.2 vs 88.7). Fitting weights to a correlation structure overfits the correlation structure; the paper drops it from the main table for instability. Read next to Kuai et al.'s +0.1pp, the corpus now has two independent attempts at dependence-aware aggregation, one that barely helps and one that is unstable.
- Dawid–Skene, the unsupervised workhorse this page's weak-supervision framing descends from, underperforms majority vote on MNLI (70.7 vs 72.0). The mechanism is the one that threatens Weaver most directly: EM estimating per-verifier error rates mistakes a correlated block for a competent one.
- On three of four datasets the best single judge beats every aggregation method, oracle-informed ones included. Kohli's own caveat is important and cuts both ways: identifying the best individual also requires gold labels, so this is not a deployable recommendation — it is a statement that the information a panel adds over its best member is, at this correlation level, negative.
The scope difference is real and should temper the transfer: Kohli's pool is nine prompted judges on a classification task, while Weaver's is ORMs, PRMs and prompted judges on reasoning generation — kind-heterogeneity, the one axis this page's second open question says nobody has measured, is still unmeasured. What transfers cleanly is the accounting discipline. Report the aggregator's gain as a fraction of the independence gap, not as a delta over majority voting; a 3pp lift over majority voting can be 1% of what was on the table.
A dependence-aware filter, built and tested against the failure mode it targets — and the regime it gets backwards (2026-09-25)#
The two pricing exercises above test whether a global dependence correction — one entanglement score, one set of weights — improves on competence weighting. Hossain, Yousefi & Lim (UCF, arXiv 2609.22512, empirical; full measurement treatment on Cross-Model Error Entanglement) build something more targeted: two filters, each matched to a specific dependence structure, plus a router meant to pick between them without knowing the structure in advance. The result sharpens this page's pricing question rather than closing it — one filter earns its keep, the other one actively hurts when the regime is misread, and neither generalizes past preference judging.
Two regimes, two filters. Global co-failure is many judges sharing the same blind spot — the case Kuai et al.'s entanglement penalty and this page's Weaver weighting both target. Vulnerable-subgroup failure is the opposite shape: errors concentrated in a small cluster of judges (here, the ones with the strongest measured position bias) while the rest of the bank disagrees with them. CorrFilter discounts an item's supporting judges by their pairwise error correlation (|S|/√(1ᵀ_S R_S 1_S)) — exactly a Ledoit-Wolf-weighted version of this page's entanglement penalty, aimed at global co-failure. Bias-Cluster instead scores by how much support an item retains outside an identified vulnerable cluster of five judges, aimed at subgroup failure. Built and calibrated on RewardBench, tested at matched retention against a 0.75-supermajority baseline on 2,000 UltraFeedback pairs with labels deliberately corrupted in each of the two patterns.
Under global co-failure, CorrFilter works and the size of the win is modest but real. No table for the controlled global-co-failure intervention is reported (the clean/biased conditions used different candidate-position assignments), but the regime-signature comparison (Table 17) shows CorrFilter beating naive consensus 0.738 vs. 0.722 under a constructed global-co-failure regime — a 1.6-point gain, in line with this page's other dependence-aware results.
Under vulnerable-subgroup failure, CorrFilter makes things worse, and the reason is diagnostic for the whole page's pricing question. At 20% position-aligned contamination, naive consensus holds 0.791 precision; CorrFilter (clean R) falls to 0.758, a −3.3pt [−4.9, −1.6] loss — while Bias-Cluster gains +2.3pt. The mechanism is the sharpest thing in the source: as subgroup contamination rises, measured bank-wide correlation falls (ρ̄ 0.22 → 0.08) and apparent n_eff rises (3.4 → 6.0), because the failure is concentrated rather than shared. A dependence score built to discount shared agreement rewards the subgroup's agreement as if it were diverse. Weaver's own filtering logic — discount correlated support — is the wrong correction whenever the true failure is concentrated rather than shared, and nothing in the bank-wide ρ̄/n_eff statistic distinguishes the two cases in advance. This is a sharper form of this page's non-monotonicity observation (top-1/5/10 ensembling helping non-monotonically): here the same aggregation family helps in one regime and actively costs precision in the other, using the same estimated R.
Under weak dependence — label noise without a shared-error structure — neither filter beats plain majority. Reversing 5–20% of labels toward style-heuristic-preferred responses degrades label quality without moving the correlation structure (eigenvector overlap with the clean bank stays at 0.99); CorrFilter and Bias-Cluster both run 0.4–1.8 points below the supermajority. Re-estimating R from 100 in-domain labels does not rescue it (Table 14). A dependence-aware filter is not free to apply "just in case" — on the regime where dependence isn't the problem, it is a net cost.
A regime router closes little of the gap it was built for, echoing Kohli's oracle-headroom result from the other page. A logistic-regression router (35 label-free statistics of the deployment votes) identifies the correct regime at 85% accuracy in single-pattern test batches — but that classification accuracy barely converts into filter-selection accuracy. On 304 mixed-regime deployments the router differs from the best fixed filter by only +0.08pt [−0.09, +0.26], while the per-instance oracle shows +0.83pt of available headroom; 57% of the router's regret comes from identifying the regime correctly but still not picking the best filter for the mixture. A preregistered non-inferiority test against a regime oracle (margin 0.5 precision points) fails in 22 of 24 comparisons. Cross-dataset and cross-bank transfer (open-weight → six-judge frontier bank) show the same shape: the router loses 0.30pt against a transferred fixed filter. Knowing the regime is not the same as knowing which correction to apply — a second instance, after Kohli's ≤11%-of-the-Condorcet-gap result, of "smarter aggregation does not rescue the deficit."
The filters do not transfer past preference judging. Screening 11 factuality and code-judging configurations against three gates (sufficient judge competence, valid regime signatures, measurable headroom over naive consensus), none pass all three — only the preference setting does. On the highest-dependence factuality bank tested (VitaminC, ρ̄ = 0.354, n_eff = 2.39/10), the tested filters retain the same items as naive consensus on ~97% of instances despite the measurable dependence, because pairwise Jaccard overlap between the filters' retained sets is 0.84–0.92. Dependence being present and dependence being exploitable by these filters are different questions, and the gap between them is wide outside the one task family (preference pairs) the method was built on.
A downstream policy check, at small scale. Training a DPO policy on majority-filtered vs. CorrFilter-filtered preferences (24.9% vs. 20.5% realized contamination) produces no measurable reward-accuracy difference at a 1.5B policy scale (+0.000 [−0.013, +0.013]); a separate, larger controlled-contamination sweep (Qwen-2.5-0.5B, 0/20/30/40% contamination) does show reward margins falling significantly (−0.42 to −0.65) from 20% contamination onward, though preference-accuracy itself stays within noise at that scale. The 4.4-point contamination difference a filtering method buys in practice is well below the contamination level (≥20%) where this paper's own downstream experiment finds a measurable effect — a caution against expecting small filtering gains to show up in a trained policy.
What this adds to the page's open question. "How much of the gain survives once the dependence is priced" now has three data points instead of one: Kuai et al.'s entangled-weight reweighting (+0.1pt over competence, three verifiers), Kohli's established-aggregator ceiling test (≤11% of the Condorcet gap, oracle-informed), and this paper's regime-matched filters (positive under the matched regime, negative under the mismatched one, and untested-to-negative outside preference judging). The accounting discipline all three converge on: report a filter's gain as a fraction of the achievable gap, on the regime it was built for, and expect it to cost precision outside that regime rather than merely fail to help.
Where this sits in the lecture's arc#
Papers 1–3 (Process vs Outcome Reward Models) spend four years making a single verifier better: label the outcome, then the steps, then the steps without humans. Weaver stops. Its bet is that the marginal return on a better verifier is lower than the marginal return on combining the ones that exist — which is test-time scaling applied to the verification half of the pipeline rather than the generation half. In Mirhoseini's recap: "we are using test time scaling, but by bringing more verifiers rather than sampling a single verifier more."
That makes it a sibling of Archon from the same lab and the previous lecture, and the pair divides cleanly: Archon composes generation and judging operations into a searched architecture; Weaver composes verifier models into one aggregated score. Both take the position that the fixed budget's shape matters more than its size, and both are prompting-and-composition rather than training.
Connections#
- The Verifiability Thesis — this is the "council of LLM judges" horizon built as an actual system, with two things the horizon lacks: a quality floor that excludes bad members, and weights fitted against real labels. The council's headroom is what LLM-Judge Validation bounds
- Process vs Outcome Reward Models — the three papers Weaver stops iterating on; ORMs and PRMs are two of the three verifier classes in its pool, and their individual imperfection is its premise
- Agreement Overstates Evidence: Error Dependence in LLM Judge Consensus — the source of this page's regime-matched filters (CorrFilter, Bias-Cluster) and their router; full dependence-measurement treatment (n_eff, frontier cross-provider correlation, the GRPO mechanism test, the pooled-vs-paired significance-test consequence) lives on Cross-Model Error Entanglement
- Cross-Model Error Entanglement — the dependence measured from the other side, with a null model and a downstream aggregator attached. BEI/CIG estimate excess co-failure and excess same-distractor collision on a ground-truth benchmark, which sidesteps the
K = σ_t² + σ_c²identification wall entirely (conditioning on error discards every agreement-because-correct), and the entanglement-penalised weights above are the first built version of this page's pricing question — worth +0.1pp over competence weighting at a three-verifier pool - LLM-Judge Validation — the measurement that contradicts its independence assumption: ρ = 0.944–0.972 (Qwen3) and 0.664–0.706 (MiniMax), both homogeneous juries, and heterogeneous juries still below independence predictions
- Stopping Under a Noisy Verifier — the corpus's other estimator with an identification boundary, and the same lesson twice. Its label-free binomial-mixture EM recovers a judge's false-accept and true-accept rates only while Youden's
J ≠ 0, and inside the collapse zone more calibration data converges more confidently on a degenerate answer (ρ̂₁ 0.27 at N = 120 → 0.077 at N = 300, true 0.609). Sunkavalli's closed form fails exactly atβ_k = σ_c²inside a positive-measure weak neighbourhood where variance blows up fifteen-fold, and answers it the way that page's held-out separation test does: with a data-only screen run before the estimate is believed (a studentized denominator,T < 4, firing on 0% of datasets at mid parameters and 100% at ρ₁ = 0.97). Both say the same thing about verification statistics — an unbiased estimator with a boundary is a trap unless something tells you where you are standing - Reference-Free Judge Over-Crediting — the analytic form of the same objection (Proposition 2: no monotone rule over a shared latent signal can reject what all judges accept) plus the optimization-pressure boundary that decides whether Weaver is a selector or a reward
- Multi-Agent Collective Intelligence — the general mechanism: width averages only independent noise, so correlated structure is a floor no ensemble size lowers
- LLM-as-a-Judge — one of the three verifier classes, and the one the negative MAV result is about: rubric-prompted judge panels underperform majority voting on two of the four datasets
- Inference-Time Architecture Search — the sibling from the same lab: Archon composes inference operations, Weaver composes verifier models, both under a budget rather than by training
- The Open-Weight Frontier Gap — the class-closure claim in its terms: an 8B generator plus ≤8B verifiers reaching 70B-majority-voting accuracy, and a 70B stack reaching o3-mini, using only open weights
- Compute-Controlled Benchmarking — the discipline the FLOP-efficiency curve half-observes: it does plot success against total inference compute, which is more than most, and the o3-mini comparison is not on that axis
- Azalia Mirhoseini — the senior author, teaching her own lab's work; verifier ensembling is her stated answer to the verification bottleneck
- CS329A: Self-Improving AI Agents (Stanford) — lecture 3, where this is the fourth and final paper
- Long-Horizon Agent Failure Signature — the un-ensembled counterexample: a single 4B trained verifier (Scout) beats six much larger frontier judges at step-level failure localization on long-horizon agent trajectories, the same result this page's pool reaches by combining many weak verifiers instead. Nobody has run Scout as a member of a Weaver-style pool, or measured whether its errors correlate with a prompted judge's the way this page's contradiction section measures for judge-vs-judge pairs
- Typed Decision Verifiers — the closest thing in the corpus to a real, independently-built Weaver-style pool: 13 trained classifiers and prompted LLM judges scored on one shared test set, rather than one paper's own ablation. It does not close this page's open question on trained-verifier-vs-prompted-judge error correlation — it reports per-system AUC, not pairwise error correlation — but it is adjacent evidence that the two kinds differ sharply in cost and mid-table ranking (frontier judges generate tokens and cost 1-3 orders of magnitude more per call while landing mid-to-bottom table against the top trained systems)
- Rationale Bootstrapping (STaR) — where this page's problem enters the training loop rather than the selection step: STaR's only filter is final-answer match, and the descendant the lecture names (V-STaR) is "put a verifier in the loop with the generator" — one verifier, which is the configuration this page argues is not enough
- Offline Multi-Step Tool-Use RL (SWiRL) — the counterexample from the same instructor's lab two lectures later: SWiRL's every training signal is a single prompted, untrained judge, with none of the pooling, quality floor or weak-supervision weighting this page argues an unreliable verifier needs
Open Questions#
- Weaver's gains are real and its independence assumption is measurably false. How much of the gain survives once the dependence is priced — i.e. what does the weight-fitting recover that a ρ-corrected aggregation would predict, and does the non-monotonic top-1/5/10 curve match Yang's beta-binomial form? Nobody has run the two together. Sharpened (2026-09-10) by A Closed-Form Estimator and Diagnostic Battery for Anchor-Judge Error Correlation, Under a Single-Common-Factor Model, which prices the pricing. The dependence is not estimable from the pool alone: inter-verifier covariance is
σ_t² + σ_c², signal plus shared error, and splitting it needs an external anchor whose own contamination is a free parameter — identified in closed form with ≥ 2 verifiers and ≥ 2 anchors, not identified at any anchor count when verifiers and anchors are all ordinal, and not identified at all when a residual is shared panel-wide (one prompt template across the pool), which is Weaver's configuration. So the question may have no within-pool answer, and the honest version of it is now two cheap experiments rather than one. (i) A Weaver pool spanning ≥ 2 model lineages already carries the family-block statistic for free: computeK_within − K_crossover the verifier score matrix and see whether the lineage residualσ_f²is non-zero — no anchors, no labels, judge metadata only. (ii) Weaver's filter-and-weight steps consume real labels, so those labels are the anchor; if they were produced by a reference model sharing the pool's biases, the designated-clean result says the failure is silent and confidently zero (ρ̂₂ = 0.502 → −0.002as the trusted anchor's own contamination runs 0 → 0.6) rather than noisy. Neither the beta-binomial half of the question nor the top-1/5/10 curve is touched. Partially answered (2026-09-22) by A Statistical Framework for Auditing Behavioral Dependence and Induced Bias in LLM Judges, which is the first source in the corpus to actually build the de-entangled aggregator and report it against the competence-only baseline rather than against majority voting. The answer, in the section above: a quality floor plus a competence weight recovers +3.4pp over majority vote, and adding the dependence penalties recovers +0.1pp more (0.881 → 0.882 accuracy, 0.891 → 0.896 precision, 500 held-out questions). So on the corpus's one measured configuration, pricing the dependence buys approximately nothing beyond pricing competence. Three reasons that is not yet the verdict: the pool is three verifiers, so the redundancy penaltyR_maverages over two others and has nothing to discriminate; the verifiers are prompted judges only, so the kind-heterogeneity question below is untouched; and the entanglement is estimated on the models' answering behaviour and used as a proxy for their verifying behaviour, a step nobody has validated. The sharp follow-up is now a pool-size sweep — report the entanglement-minus-competence delta atM_J= 3, 5, 7, 9 and see whether it rises. Advanced again (2026-09-22) by Kohli, who supplies the denominator the question was missing. Measured against a Condorcet independence ceiling rather than against majority voting, established aggregation closes at most 11% of the gap with oracle access to gold labels: accuracy-weighted voting (this page's filter-and-weight step, stripped to its simplest form) closes under 1% on MNLI, Dawid–Skene underperforms majority vote there, and phi-optimal weighting — inverting the correlation matrix, the most direct possible form of pricing the dependence — is best on two datasets and worse than plain voting on a third. So the answer now has a shape: the recoverable fraction is small and the correlation-aware variants are the unstable ones. Still open on this page's own configuration, for the same three reasons as before plus one new one: Kohli's pool is nine prompted judges on classification, so kind-heterogeneity remains untested, and his panel size is fixed at nine, so it does not run theM_Jsweep either. The reporting discipline it does settle: state an aggregator's gain as a fraction of the independence gap, since a 3pp lift over majority voting can be 1% of what was available. - Is error correlation across kinds of verifier — trained reward model vs prompted judge — materially lower than across judges? Every measurement in this wiki is judge-to-judge, which is the case most favourable to the objection and least representative of Weaver's pool.
- Does the distilled ~400M scorer inherit the ensemble's robustness or only its accuracy? A single small model reproducing a pool's verdicts has, by construction, no diversity left to lose — which is fine for a static selector and is exactly the object optimization pressure would attack first.
- Hossain, Yousefi & Lim's CorrFilter helps under global co-failure and costs 3.3 points under vulnerable-subgroup failure using the same estimated correlation matrix, and their regime router closes little of that gap (non-inferiority against a regime oracle fails in 22 of 24 comparisons). Does Weaver's own weight-fitting — which does not distinguish the two regimes at all — inherit the subgroup-failure cost, or does fitting weights per-verifier (rather than per-item, as CorrFilter does) sidestep it? Untested: nobody has run a vulnerable-subgroup intervention against Weaver's actual pipeline.
Sources#
-
A Statistical Framework for Auditing Behavioral Dependence and Induced Bias in LLM Judges — Kuai, Jiang, Zhu, Wang, Wu, Li, Zhang, Liu, Tu, Fan & Zhou (Texas A&M / Marquette / Utah), A Statistical Framework for Auditing Behavioral Dependence and Induced Bias in LLM Judges, arXiv 2604.07650 v2, 2026-08-09, 19pp, COLM 2026,
empirical. Cited here for §3.3 and §B.4 (the entanglement-penalised weightw_m^(S) ∝ q_m^κ exp(−η₁R_m − η₂T_m^(S)), theE(i,j) = λ·BEI + (1−λ)·CIGcombination, and the 500/500 calibration/held-out split with all four parameters frozen before evaluation) and §4.3 / Table 3 (the three aggregation arms). Table 3 was re-reconciled againstpdftotext -layoutat compile time — the ingest worker's verify run stood down before confirming any table — and matches cell-for-cell; the +0.1pp entanglement-minus-competence delta is arithmetic over its rows, not a figure the paper states. Full treatment, the audit half, and the COI and parse notes on Cross-Model Error Entanglement and inwiki/sources.md -
A Closed-Form Estimator and Diagnostic Battery for Anchor-Judge Error Correlation, Under a Single-Common-Factor Model — Veerendra Kumar Sunkavalli (Independent Researcher, no institutional affiliation; single author), A Closed-Form Estimator and Diagnostic Battery for Anchor-Judge Error Correlation, Under a Single-Common-Factor Model, arXiv 2609.08826, 2026-09-08, 11pp,
empirical. Cited here for §3 (Assumptions 1–2, the moment structureK = σ_t² + σ_c², Theorem 1 and Corollary 1's exact boundary), §4 (recovery simulations, Table 1's boundary blow-up, Table 2's non-monotone asymmetry bias), §5 (Tests A/B/C, Table 3's operating characteristics, the family-blocked estimator and the two blind spots), §6 (bootstrap coverage, the weak-identification screen, the ML comparison and the CT-C(M−1) degradation series), §7 (the ordinal identification hierarchy and both real-panel Test A results) and §8 (what is and is not established). -
Evidence handling. The
empiricaltier is kept but is narrower than it looks and every claim above is scoped accordingly: the estimator is validated in simulation and semi-synthetically under oracle calibration, never on a real panel, because both real panels tested were rejected by the paper's own adequacy pre-test and no qualifying panel exists. The diagnostics are validated on real data in the rejecting direction only — specificity on a real adequate panel is untested. The real measurement content is genuine (431 HANNA human ratings; 5,996 parsed verdicts from six real judges) and it is all negative. Noρ_kfigure here is a measurement of anything in the world. -
COI: none identifiable, and that is itself the note. Single independent author, no lab, no funding statement, no product; the models evaluated are six third-party judges with no competitive relation to the author. The countervailing risk is the ordinary one for unaffiliated single-author preprints — no internal review, no replication, and a
SymPy-verifiedproof appendix that nobody else has run. Code, pre-registration (with logged amendments) and a checksummed verdict cache are shipped, which is more reproducibility infrastructure than mostempiricalsources on this wiki carry. -
Parse note. PDF-derived (docling 2.126.0 / docling-mlx 0.1.1, 11pp, 4 tables, formula engine mlx). All math except equation (1) is flattened inline Unicode — Assumption 1's anchor equation lost its fraction bar in both docling and
pdftotextand is written above asA_k = t + (β_k/σ_c²)·c + u_k, reconstructed fromβ_k:= Cov(A_k, c)and confirmed against the PDF's layout output; treat no inline formula in that raw as exact. Table 3 (battery operating characteristics) was column-shifted and Table 4 (the decision-aid table) collapsed at ingest, both repaired; Table 3 was independently re-verified againstpdftotext -layout -f 5at compile time because this section quotes its rows. Tables 1–2 parsed exact. -
Agreement Overstates Evidence: Error Dependence in LLM Judge Consensus — Elias Hossain, Niloofar Yousefi & Ser-Nam Lim (UCF), arXiv 2609.22512 (2026-09-18),
empirical. Cited here for §2.2–2.3 (CorrFilter and Bias-Cluster definitions, the regime router and direct selector), §4.4 and Tables 3, 14, 17 (filter precision under weak dependence, global co-failure and vulnerable-subgroup failure, reconciling Table 3's collapsed weak-dependence row against Table 15 — see the parse note on Cross-Model Error Entanglement), §4.5 and Table 20 (router vs. fixed-filter precision, the regret decomposition), App. J (the non-inferiority test against a regime oracle), App. K (the 11-task cross-domain screen) and App. M.5 / Table 27 (the DPO downstream contamination check). Full source citation, evidence handling and parse note on Cross-Model Error Entanglement -
CS329A Self-Improving AI Agents — Part 3: Robust Verification — Stanford CS329A lecture 3, Azalia Mirhoseini (delivered 2025-09-29, published 2026-08-03,
practitioner-opinion, YouTube auto-caption transcript, ~10.7k words). Paper 4 of four: Shrinking the Generation-Verification Gap with Weak Verifiers (Weaver, Stanford, 2025) plus its distillation follow-up. Used for the weak-verifier definition, the top-1/5/10 non-monotonicity and the naive-Bayes/logistic-regression weighting, the score→weight→select pipeline and the load-bearing filter step, the Snorkel weak-supervision lineage, the n·k·m formulation and the conditional-independence assumption stated verbatim, the four-arm comparison including the negative MAV result, the ~40%→70% and 86.2%/o3-mini figures, the 8B-and-70B class-closure claims, and the ~400M / ~97% / 99%+ distillation numbers. The paper is not inraw/— every figure is read off a slide by ASR and is approximate. COI: total. Mirhoseini is the senior author of the work she is teaching, and says so. The "7B / 7TB" renderings in the class-closure passage are ASR corruption of 70B and are carried as such -
Inside the JEV Ecosystem: 13 Answer Verifiers on One Test Set — Proto_AGI (
mayafree), HuggingFace community article, published 2026-09-20,empirical. Cited here only for the Connections entry: the closest real-world instance of a multi-vendor verifier pool (13 trained classifiers and LLM judges) scored on one shared test set — but it reports per-system AUC, not pairwise error correlation, so it does not answer this page's open question on trained-verifier-vs-prompted-judge error correlation. Full treatment on Typed Decision Verifiers
Cited by 23
- Cross-Model Error Entanglement×6
Sunkavalli's ρ_k (Weak Verifier Ensembling) · judge scores, as covariance · no · yes, ≥ 2 anchors ·…
- LLM-Judge Validation×4
Weak Verifier Ensembling — the system this page's Finding C bounds, and the most direct collision…
- Process vs Outcome Reward Models×4
cs329a 03 robust verification — Stanford CS329A lecture 3, Azalia Mirhoseini (delivered 2025-09-29,…
- The Verifiability Thesis×4
cs329a 03 robust verification — Stanford CS329A lecture 3 (Azalia Mirhoseini, delivered 2025-09-29,…
- The Price of Mixing Agents, and the Principal Nobody Counted×3
Weak Verifier Ensembling renders Yang's error-correlation figures as "ρ = 0.944–0.972 for repeated…
- LLM-as-a-Judge×3
Weak Verifier Ensembling — judges as one of three verifier classes in an aggregated pool, plus a…
- Azalia Mirhoseini×2
Weak Verifier Ensembling — Weaver, her lab's fourth: combine imperfect verifiers rather than train…
- CS329A: Self-Improving AI Agents (Stanford)×2
Steps 1–3 live on Process Vs Outcome Reward Models; step 4 on Weak Verifier Ensembling. Three…
- Large-Scale Test-Time Compute×2
cs329a 03 robust verification — Stanford CS329A lecture 3 (Azalia Mirhoseini, delivered 2025-09-29,…
- Open Questions Backlog×2
Weak Verifier Ensembling ×3 (oldest 43d) — Is error correlation across kinds of verifier — trained…
- Rationale Bootstrapping (STaR)×2
V-STaR — put a verifier in the loop alongside the generator, trained together, instead of relying…
- Compute-Controlled Benchmarking
Weak Verifier Ensembling — a rare half-observance: Weaver plots success rate against total…
- Inference-Time Architecture Search
Weak Verifier Ensembling — the sibling from the same lab and the next lecture, dividing cleanly:…
- Long-Horizon Agent Failure Signature
Weak Verifier Ensembling — a single small trained verifier outperforming a pool of much larger…
- Evals & Benchmarks
Weak Verifier Ensembling — Weaver (Stanford, 2025): stop training a better verifier and combine the…
- Multi-Agent Collective Intelligence
Weak Verifier Ensembling — the same mechanism at the scale of a verifier pool rather than an agent…
- Offline Multi-Step Tool-Use RL (SWiRL)
The judge is the ceiling. Nothing is trained, nothing is calibrated, nothing is ensembled.…
- The Open-Weight Frontier Gap
Weak Verifier Ensembling — the gap closed from the inference side rather than the training side,…
- Reference-Free Judge Over-Crediting
Weak Verifier Ensembling — Proposition 2's most prominent target: a practitioner-opinion system…
- Reward Hacking
Weak Verifier Ensembling — an aggregated verifier with an explicit quality floor and learned…
- Same-Model Review Blindness
Weak Verifier Ensembling — the same uncited claim, restated in the lecture where it collides with…
- Stopping Under a Noisy Verifier
Weak Verifier Ensembling — the same failure shape in a different estimator, and the answer this…
- Typed Decision Verifiers
Weak Verifier Ensembling — this study's 13-system, one-shared-test-set design is the closest…
Related articles
- Process vs Outcome Reward Models
The four-year arc of trained LLM verifiers as taught in CS329A lecture 3: OpenAI's GSM8K verifier (score the finished s…
- LLM-as-a-Judge
Using one LLM to grade another's outputs against criteria/rubrics; DRACO's protocol is per-criterion binary MET/UNMET +…
- The Verifiability Thesis
LLMs automate what you can *verify* as computers automate what you can *specify*; RL verification rewards → jagged peak…
- Large-Scale Test-Time Compute
Noam Brown's thesis that model capability is now a function of inference budget (tokens/cost/time): with good scaffoldi…
- Tree Search over Agent Trajectories (LATS)
LATS (ICML 2024): run Monte Carlo Tree Search over an agent's action trajectories instead of committing to one — sample…